ZDNET’s key takeaways
- The AX9 Max Mini PC is ideal for running local AI.
- With a lot of power to spare, it will not be hidden.
- This machine runs local AI directly or from your LAN.
I’ve run AI on almost every machine I own, with varying degrees of success. Of course, the complexity of the task usually dictates how well it runs on any desktop or laptop. I could open up locally installed AI and ask a basic question, and that question would be answered almost instantly. Or, I could ask locally installed AI to write an application for me and watch it stall until processing is complete.
Also: Inside Linux-AI OS: I tested a distro with built-in local AI
That is the usual case with locally installed AI. This is especially the case if the machine in question does not have an NVIDIA GPU. So, when the company asked me to give its latest AMD-based mini PC specifically for AI a try, my first thought was that I would see similar results as I have seen with other non-NVIDIA machines. I was wrong. Totally wrong.
What is the AX9 Max Mini PC?
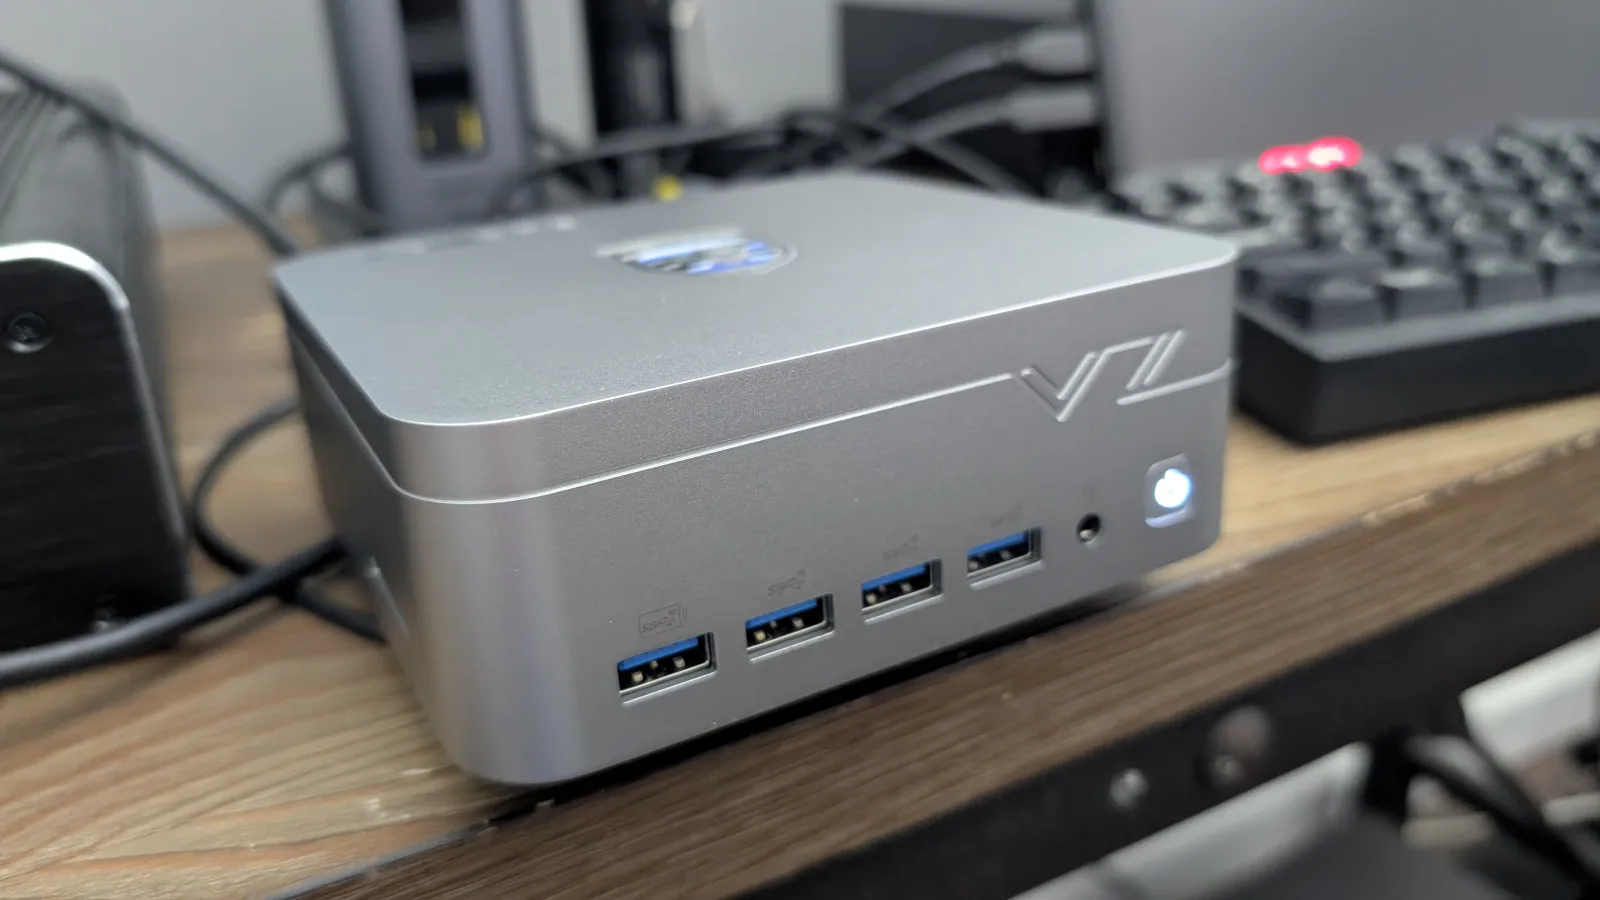
The AX9 Max Mini PC is a small form factor PC powered by an AMD Ryzen AI 9 HX 470, a Radeon 890M GPU, with 32 GB SO-DIMM RAM and a 1 TB M.2 SSD. The PC measures 5.3 x 5.2 x 2.3 inches, so it doesn’t take up much space.
The description of the device says the AX9 Max Mini has NPU capable of processing up to 86 TOPS of total AI performance and is designed for local AI workflows. It supports LM Studio, Ollama, and AMD GAIA to run compatible Qwen, Llama, Gemma, and DeepSeek models locally, reducing reliance on cloud-based AI services and keeping sensitive data on the device.
How did I test the AX9 Max Mini PC?
The first thing I did was to install Fedora Linux over the pre-installed Windows OS. I am much more comfortable with Linux than Windows and felt that I could be best positioned to judge the hardware with the open-source OS.
As well: 7 things every Linux beginner should know before downloading their first distro
After the 2 minutes it took to install Fedora, I was ready to set up the machine for the real test. For that I installed the Ollama GUI frontend, Moose, with the command:
flatpak install flathub io.github.moooossee.MooseOnce that was installed, I had Moose download and install Ollama and then draw the qwen3-coder:30b model (because I knew I was going to use Ollama to generate a web app for testing).
Now that the machine was ready for testing, it was time.
The test
I asked Ollama, Moose, and qwen3-coder to generate a web app that would accept user input for theater costume measurements, save it to a database, and allow the user to register and save their information.
I fully expected the machine to churn on this one for a while before slowly spitting out the code. To my surprise, it immediately started responding and eventually generated a web app that was about 1,500 lines of code.
I had my doubts.
Nevertheless, I installed Apache on the machine (another reason I installed Linux over Windows), copied the code into a file I called costume.html, moved the file to the Apache document root (/var/www/html), fired up my browser, and pointed to it.
 Jack Wallen/ZDNET
To my surprise, the web app worked! Not only did it work, but it worked very well. I had to fix several problems in the code (specifically problems with the database commands), but once I took care of that, the app worked perfectly.
The biggest surprise for me was that, when Ollama went through the creation of the various files for the app (config.php, login.php, logout.php, measurements.php, signup.php), I was able to use the machine as if nothing happened. Even with my System76 Thelio (which includes a Ryzen 9 7900X 12-core CPU, RX 7600 Navi 33 GPU, and 32 GB of RAM), I would experience lags, stutters, and even crashes when trying to build an app with Ollama. The AX9 Max took on the task without so much as a blink of the digital eye.
Also: This local AI quickly replaced Ollama on my Mac – here’s why
The difference between the two machines is that the AX9 Max Mini CPU includes an NPU (AI Engine): XDNA 2 architecture, which delivers up to 86 total AI TOPS (tera or trillion operations per second), measuring how many raw AI calculations a processor can run in one second. That gives it the extra beef it needs to process AI without draining system resources for other tasks.
The conclusion is simple: the AX9 Max Mini is a small form factor PC that is ideal for running local AI, not only for general chat, but for much more complex processes, such as building viable applications, without bringing the system to a screeching halt.
 Jack Wallen/ZDNET
This little machine seriously impressed me; so much so that I could see myself using this as a dedicated AI machine in my home lab. In fact, I configured Ollama so that I could connect to any machine on my LAN, so I didn’t have to run local AI on my primary desktop or my laptop, and it worked perfectly. I will say this though: running Ollama over a LAN is not nearly as fast as running it directly on the machine. However, I tested the same setup with my System76 Thelio, and the speed at which the VZmore can produce output from a remote connection is significantly faster.
Final thoughts
If you want to use local AI but don’t have the space for a massive desktop PC, the AX9 Max Mini PC is a beast that will serve your local AI needs quite well. At $1,499, you’d be hard-pressed to find a better deal for an AI-ready PC.
As well: I tried a Claude Code competitor that is local, open source and completely free – how it went
You also get plenty of ports to add peripherals and even connect up to four displays.
Tech specifications
- Processor (CPU): AMD Ryzen AI 9 HX 470 (Zen 5 architecture; 12 cores / 24 threads: 4 Zen 5 + 8 Zen 5c)
- Graphics (GPU): AMD Radeon 890M (16 computing units, up to 3.1 GHz)
- AI NPU: Up to 55 NPU TOPS (86 total system AI TOPS)
- Memory (RAM): 32GB DDR5 (supports expansion up to 256GB DDR5)
- Storage: 1TB PCIe 4.0 SSD (supports dual PCIe 4.0 expansion up to 5TB)
- Cooling: V-Cooling Next-Gen Thermal Architecture (vapor chamber VC, 360 ° bottom recording, ~38 dB silent operation, up to 65W sustainable TDP)
- Operating system: Windows 11 Pro
- Display: Quad-display support via dual 40Gbps USB4 and dual HDMI 2.1 (up to 8K output)
- Networking: Dual 2.5G LAN ports, Wi-Fi 7
- USB ports: 2x USB4 (40Gbps), 6x USB-A ports
- Other: SD 4.0 card reader

See full bio