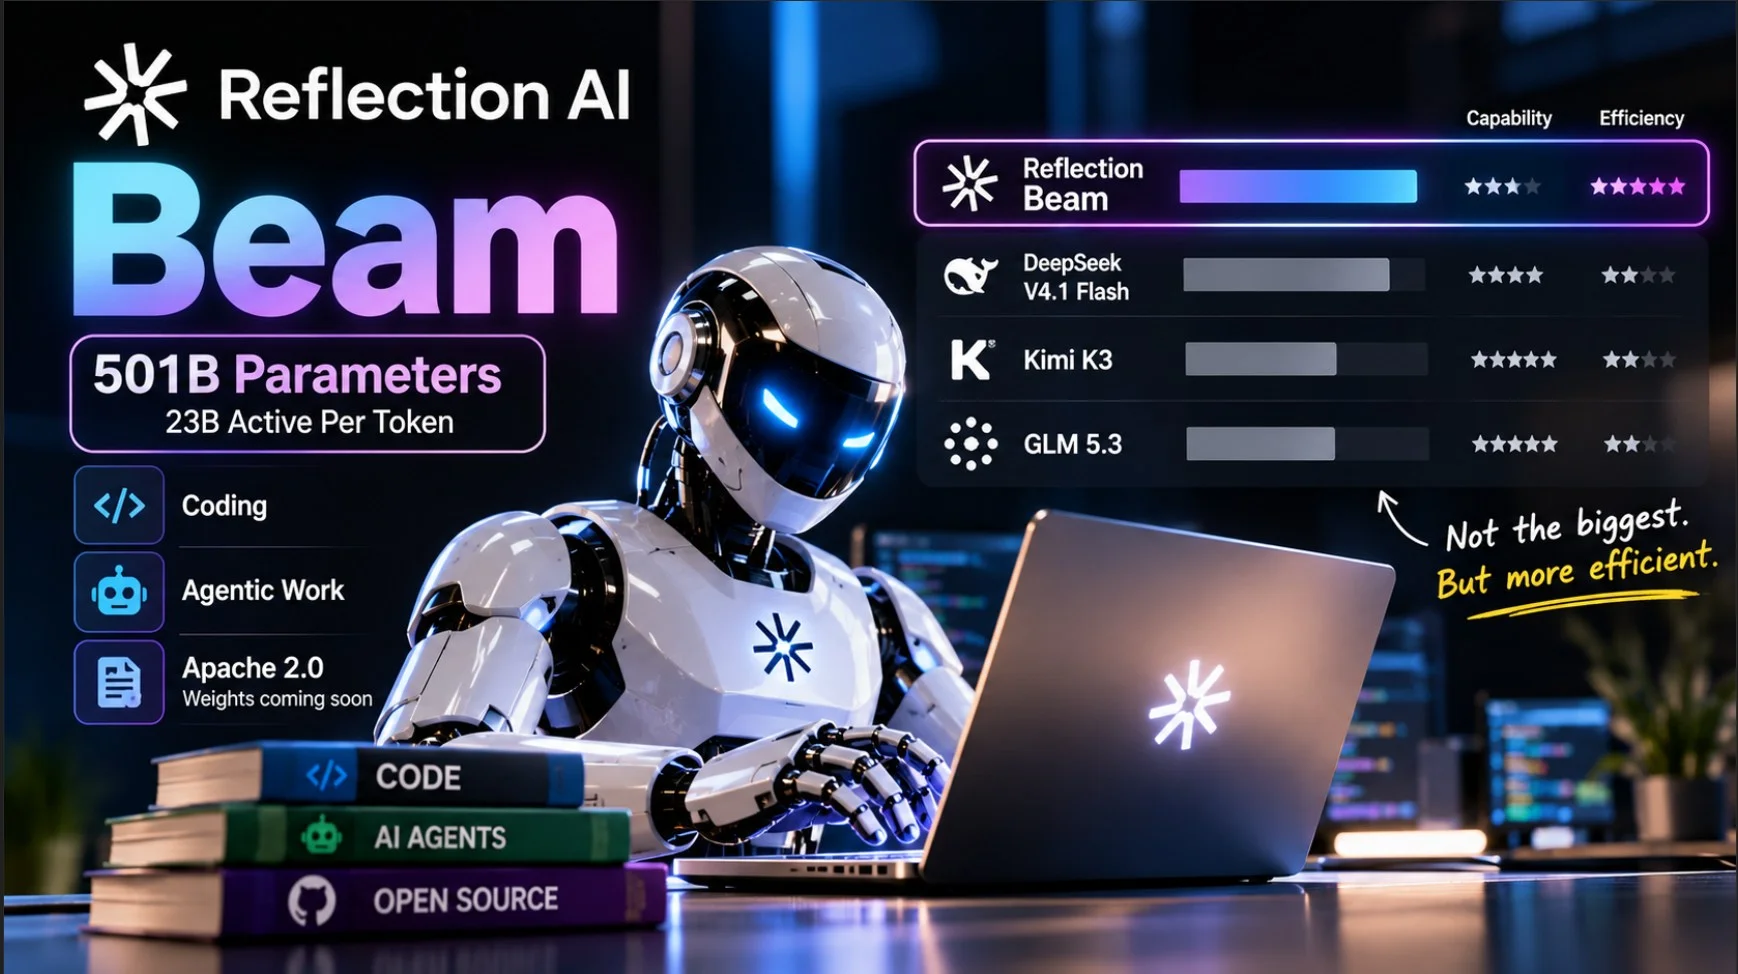
Reflection AI announced Beam on October 5, a 501 billion parameter mix-of-experts model with 23 billion assets per token, built for coding and agent work. Weights will come under Apache 2.0 later this month.
Read the benchmark table reflection published, the picture is more interesting than an immediate victory. DeepSeek V4.1 Flash, Kimi K3, and GLM 5.3 beat Beam on most ranks. Reflection says so itself: where border open models like The Kimi K3 remains ahead on raw capacity, BThe advantage of eam is efficiency in inference time.
That’s an unusually honest frame, and it’s the actual pitch.
Where Beam lands
| Benchmark | Beam | Best competitor in the table |
|---|---|---|
| SWEBench Verified | 80.9 | A 77.6 |
| Terminal Bench v2.1 | 80.1 | DeepSeek V4.1 Flash 90.6 |
| SWEBench Multilingual | 78.0 | Nemotron 3 Ultra 67.7 |
| SWE Bench Pro v2-Hard | 77.2 | Kimi K3 88.2 |
| SWE Bench Pro v1 | 65.5 | Qwen 3.8 Max 67.7 |
| DeepSWE v1.1 | 44.4 | DeepSeek V4.1 Flash 74.2 |
| SWE Atlas Codebase QnA | 34.6 | Kimi K3 68.0 |
Beam leads to SWEBench Verified and SWEBench Multilingual. It takes the rest, sometimes hard.
The efficiency claim is the counterweight. Reflection says that Beam matches GLM-5.2 on advanced reasoning benchmarks, while using three to four times less inference computation, with a wider gap against models in the two trillion parameter class than Qwen 3.8-Max. His cadre is more intelligence per token.
The measurement method is important here. Reflection estimates calculate as approximately twice the active parameter count multiplied by mean generated tokens, excluding prompt prefilling, attention operations, and service overhead. It calls this an estimated comparison rather than measured inference costs, and uses Artificial Analysis and DataCurve to figure out rival models.
The training run is the real story
The numbers behind Beam are significant enough to matter on their own.
Pre-training continues 6,144 NVIDIA GB300 NVL72 GPUs in less than four weeks, over 23.8 trillion curated tokens. Reinforcement learning then used 10,500 GB300 GPUs for four weeks, generating more than 100 million rollouts on up to 256K context, against about a million purpose-built environments and about 1.3 billion sandboxes. Reflection thinks this is one of the biggest RL runs any open lab has done.
His most interesting claim over that run: the ability continued to improve as RL calculation increased, with no sign of a plateau.
The infrastructure figures are the kind that are usually kept in-house. An average of 110,000 concurrent rollouts, up to 170,000 concurrent sandboxes, more than one billion sandbox creation requests across two clouds and four regions, new weights reaching the inference fleet in a median of 12 seconds, 71 inference incidents handled without killing the training job, and 92.
Skills that showed up uninvited
A discovery is worth more than the benchmarks.
Reflection trained on reasoning, software engineering, and terminal tasks without browsing tasks in the mix, and browser performance improved overall. Given web access, the model began to search, query other language models and use OCR APIs to read documents without being trained to do anything.
This transfer is why the demos look wider than a coding model should. Beam built a live NYC subway map by finding MTA documentation themselves, checking authentication requirements, and locating map geometry. Joined in OpenCode, it unsloth researched the documentation and wrote a fine-tuning notebook for Gemma-4, which improved the holding accuracy of this model by 66.5%.
Beam is text-only, but handles other modalities if something converts them to text first.
There is also a reasoning effort parameter that allows users to trade response length against skill per task.
Context and security
Midtraining extended the context window to one million tokens.
Regarding security, reflection trained a separate alignment model from the same pretrained checkpoint and merged it with the capability model through multi-learner on-policy distillation. Its principles sit in three layers: rules Beam must not break, qualities that should consistently satisfy it such as the recognition of uncertainty, and a standard interaction style.
The safety training used deliberative alignment, building each other over rounds by generating cues that produce harmful or over-refusing behavior and knocking successful attacks back into the next round.
Reflection says it will open-source the security assessments it developed internally, which is a more useful commitment than publishing the results alone.
Availability
Beam is in the last red teaming, with early access through a waiting list on the Reflection platform. Weights, technical report, model map, and developer artifacts will follow later in October under Apache 2.0, in addition to distribution partners and integrations with open-source harnesses.
Reflection describes Beam as advancing the western open weight frontier, which is an accurate phrase. It does not claim to be the best open model. It claims the best that did not come from China, with a cost argument attached.